If you build with AI agents, you may recognize a tempting rule: if an agent can do it, let the agent do it. Your workflow gains another capable helper, so adding one more agent can feel like progress.
But capability is not the same thing as necessity.
The question I now find more useful is this: what part of your problem do you already understand well enough to stop reasoning through it every single time?
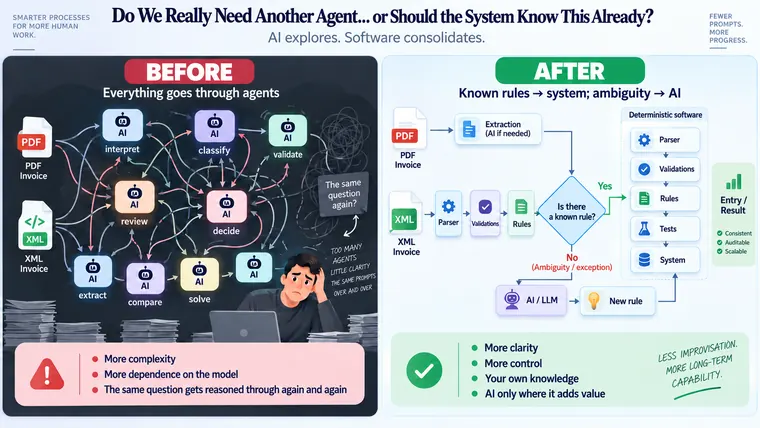
For example, a task may already be stable, repeatable, and objectively verifiable. In that case, deterministic software may be the better default. When the task still depends on ambiguity, context, exceptions, or unstructured information, an AI agent starts to earn its place.
In other words, this is not about using less AI, but about using intelligence where uncertainty still exists. That boundary is becoming one of the most useful design decisions I make.
An electronic invoice makes the difference visible
Imagine an electronic invoice. If all we receive is a PDF, a machine has to reconstruct a surprising amount of meaning. It must find the supplier and customer, recognize the table, separate taxes from discounts, and connect each value with its concept. A multimodal model can be extremely useful there.
Now add another input: the structured XML behind the invoice.
A large part of the interpretation problem disappears. The supplier already has a field. The date has a field. Taxes have defined fields. Product lines have hierarchy. Values arrive associated with what they mean.
This is not merely a convenient thought experiment. The European EN 16931 eInvoicing standard defines a semantic model for the core elements of an electronic invoice. It maps that meaning into structured syntaxes such as UBL and CII. That means some workflows already contain much of the meaning a machine needs.
So the question changes: why ask an LLM to rediscover something the system already knows?
Instead of asking a model to reinterpret those fields, we can parse the XML, verify totals, apply explicit rules, and transform the data into our own model. If the same condition should produce the same answer every time, we can test that answer directly.
I do not need creativity there. I need certainty.
AI agents vs. deterministic software: where each one earns its place
The useful distinction is not “AI versus traditional software,” but known logic versus meaningful uncertainty. Deterministic software means the answer follows rules we already understand and can test.
The same workflow can contain both.
Some parts may be well defined. We can check identifiers against known constraints. We can apply business rules consistently. We can verify calculations. A workflow can also have explicit states and transitions.
Then something different appears: an ambiguous description, a difficult classification, or a new edge case with no rule yet. Now we actually have a question. That is where AI becomes more valuable. It can interpret, compare possibilities, and help investigate unstructured information. A human can validate the result, and the process moves on.
Current guidance from the companies building these systems reflects the same boundary. OpenAI recommends agents especially when deterministic or rule-based approaches fall short. It also notes that a deterministic solution may be enough in other cases.
Anthropic draws a similar line. Predefined workflows provide predictability and consistency for well-defined tasks. Agents become useful when the task needs flexibility and model-driven decisions.
That does not give us a universal formula. It gives us a better question.
When an exception keeps returning, it becomes knowledge
Suppose the same exception comes back. Then again. Then again.
At some point, it is not much of an exception anymore. We have learned something.
The next question is whether that learning should remain only in a conversation or become a permanent system capability. We can call that consolidation: turning a recurring lesson into something the system can reuse. I think of the progression like this:
known → software

unknown → AI

recurring unknown
→ learning
→ rule
→ test
→ software
The agent does not disappear; it moves to the next frontier. That matters because the system keeps the lesson while the agent keeps exploring.
A simple phrase helps me remember the distinction: AI explores the frontier; software consolidates the territory.
Learning should leave something behind
We talk a great deal about agent memory, persistent context, conversation history, and knowledge bases. All of them can be useful. But another form of memory often matters more in production: making what we learned change the system.
If we solve an exception, discover a general rule, and turn it into tested code, the next run does not have to reconstruct the entire conversation. The knowledge has been absorbed into something we can inspect, test, version, and reuse.
That changes how I think about system maturity. A system that is still exploring will naturally need interpretation. But once a recurring decision becomes understood, we can move part of that knowledge into rules, contracts, validations, tests, schemas, and explicit state.
This does not mean removing AI. It means reserving it for places where intelligence is still doing real work.
NIST gives us a practical reason to keep that boundary visible. Its Generative AI Risk Management Profile defines confabulation as false or erroneous content presented with confidence. It also recommends testing and evaluation practices, including comparisons with known ground truth when appropriate.
That does not make LLMs poor automation tools. It suggests something more useful: when an objective check exists, use it.
The model can propose. The system can still verify.
From a human correction to a system rule
Coding agents make this especially interesting to me.
For years, many domain experts understood processes that were technically automatable but difficult or expensive to translate into software. They knew what should happen, which exceptions mattered, when a workflow should stop, and what a missing field meant. Turning that knowledge into working code still required a long translation chain.
In my own work, coding agents are shortening part of that distance.
A domain expert can now work with an agent without mastering every library or implementation detail. But one capability remains difficult to outsource: knowing when the result is wrong.
The expert can say: “That is not the rule.” “There is an exception here.” “That field does not mean what you think it means.” “This process should stop now.”
The most valuable part comes next.
If that correction stays only in the chat, we learned something—but the system may not have learned it. If we turn the correction into a rule, test, validation, or contract, the next execution starts from a higher level.
That resembles an old engineering idea: Plan, Do, Check, Act. Try, inspect, correct, consolidate, and run the cycle again. ISO describes PDCA precisely as a cycle of continual improvement for processes and systems.
The tool is new; the logic of continuous improvement is not.
This is also part of the broader progression I described in How to Work Better with AI: better prompts eventually become better context, clearer criteria, tools, tests, workflows, and systems.
The agent can change; the capability should remain
There is another advantage to consolidating what we learn.
I may build with one model today and switch providers tomorrow. A better tool may appear. The architecture may change. If operational knowledge lives mainly inside prompts, conversations, and agent-specific behavior, part of the system remains tied to that tool.
But if the work turns that knowledge into rules, code, tests, schemas, workflows, and structured data, the relationship changes.
The agent can change; the capability remains.
That distinction matters more to me the longer I build with these systems. AI can help create the asset without having to become the asset. A model may help us discover a rule. Once the rule is clear, I would rather inspect it, test it, version it, and move it.
Before adding another AI agent, try this filter
The next time a workflow seems to need “another agent,” I use a simple framework: five questions:
- Is the input already structured? If a field, schema, API, or explicit format already represents the information, we may not need an LLM to interpret it again.
- Which part of the decision is governed by a known rule? If the same condition should produce the same response, it may be a candidate for deterministic code.
- Can the result be checked objectively? If yes, keep that verification deterministic even when a model participates earlier.
- Is the exception still an exception? If it keeps returning and we understand the pattern, it may be ready to consolidate.
- If I switch models tomorrow, what knowledge remains? The answer reveals how much learning actually belongs to the system.
These are not commandments. They are a filter.
Sometimes the answer will still be “I need an agent.” Good. That is exactly where I want one. Other times, we may discover that we are spending intelligence to repeatedly make a decision we already understand.
For a while, the dominant question was: What else can I do with agents?
I still ask it. But I now put another question beside it: What is an agent doing today that should no longer require an agent tomorrow?
Not because I want less AI. Because I want every cycle to leave something behind: a clearer rule, a new test, a stronger contract, one less ambiguous exception, a capability that survives after the conversation ends.
AI explores the frontier. We validate what we learn. Software consolidates the territory. Then the frontier moves again.
So the next time you think, “I could put another agent here,” try a more uncomfortable question first:
Do you actually need intelligence here—or do you already understand the answer well enough to turn it into software?
References
- European Commission, EN 16931 / European standard on eInvoicing: semantic data model and structured syntaxes for electronic invoices. https://ec.europa.eu/digital-building-blocks/sites/spaces/DIGITAL/pages/467108926/Compliance+with+eInvoicing+standard
- OpenAI, A practical guide to building agents: guidance on when agentic approaches add value and when deterministic solutions may suffice. https://openai.com/business/guides-and-resources/a-practical-guide-to-building-ai-agents/
- Anthropic, Building Effective AI Agents: distinction between predictable workflows and agents for flexible, model-driven decision-making. https://www.anthropic.com/engineering/building-effective-agents
- NIST, Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile (NIST AI 600-1): confabulation, human oversight, testing, evaluation, validation and verification. https://doi.org/10.6028/NIST.AI.600-1
- ISO 9001, The process approach in ISO 9001:2015: Plan-Do-Check-Act as a cycle of continual improvement. https://www.iso.org/iso/iso9001_2015_process_approach.pdf